


嵌入是具有语义意义的信息压缩表示。它们可用于相似度搜索、零样本分类,也可以用来训练新模型。相似度搜索的应用场景包括电商中的相似商品检索、社交媒体中的内容搜索等。
本笔记本介绍如何使用 🤗 Transformers、🤗 Datasets 和 FAISS,从特征提取模型创建嵌入并建立索引,再利用它们进行相似度搜索。
先安装所需库:
!pip install -q datasets faiss-gpu transformers sentencepiece本教程使用 CLIP 提取特征。CLIP 通过联合训练文本编码器和图像编码器,将两种模态联系起来,是一项开创性的模型。
import torch
from PIL import Image
from transformers import AutoImageProcessor, AutoModel, AutoTokenizer
import faiss
import numpy as np

device = torch.device("cuda" if torch.cuda.is_available() else "cpu")

model = AutoModel.from_pretrained("openai/clip-vit-base-patch16").to(device)
processor = AutoImageProcessor.from_pretrained("openai/clip-vit-base-patch16")
tokenizer = AutoTokenizer.from_pretrained("openai/clip-vit-base-patch16")
加载数据集。为了保持笔记本轻量,这里使用较小的图像描述数据集 jmhessel/newyorker_caption_contest:
from datasets import load_dataset

ds = load_dataset("jmhessel/newyorker_caption_contest", "explanation")
查看一个样本:
>>> ds["train"][0]["image"]ds["train"][0]["image_description"]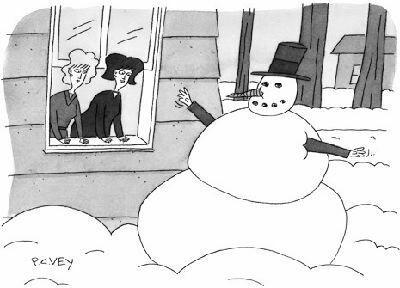
不必自己编写用于嵌入样本或创建索引的函数。🤗 Datasets 与 FAISS 的集成已经封装了这些过程。只需使用数据集的 map 方法,就能创建一个新列,保存每个样本的嵌入。下面先从描述文本列提取文本特征:
dataset = ds["train"]
ds_with_embeddings = dataset.map(
    lambda example: {
        "embeddings": model.get_text_features(
            **tokenizer([example["image_description"]], truncation=True, return_tensors="pt").to("cuda")
        )[0]
        .detach()
        .cpu()
        .numpy()
    }
)
也可以用相同方式生成图像嵌入:
ds_with_embeddings = ds_with_embeddings.map(
    lambda example: {
        "image_embeddings": model.get_image_features(**processor([example["image"]], return_tensors="pt").to("cuda"))[
            0
        ]
        .detach()
        .cpu()
        .numpy()
    }
)
现在为每一列建立索引。首先是文本嵌入:
# create FAISS index for text embeddings
ds_with_embeddings.add_faiss_index(column="embeddings")
然后是图像嵌入:
# create FAISS index for image embeddings
ds_with_embeddings.add_faiss_index(column="image_embeddings")
使用文本提示查询数据
现在可以用文本或图像查询数据集,取得其中的相似样本:
prmt = "a snowy day"
prmt_embedding = (
    model.get_text_features(**tokenizer([prmt], return_tensors="pt", truncation=True).to("cuda"))[0]
    .detach()
    .cpu()
    .numpy()
)
scores, retrieved_examples = ds_with_embeddings.get_nearest_examples("embeddings", prmt_embedding, k=1)
>>> def downscale_images(image):
... width = 200
... ratio = width / float(image.size[0])
... height = int((float(image.size[1]) * float(ratio)))
... img = image.resize((width, height), Image.Resampling.LANCZOS)
... return img
>>> images = [downscale_images(image) for image in retrieved_examples["image"]]
>>> # see the closest text and image
>>> print(retrieved_examples["image_description"])
>>> display(images[0])输出的图像描述如下:
['A man is in the snow. A boy with a huge snow shovel is there too. They are outside a house.']
这段描述的意思是:一个男人站在雪中,旁边有个拿着巨大雪铲的男孩,他们在一所房子外面。
使用图像提示查询数据
图像相似度推理的过程类似,只需要改为调用 get_image_features:
>>> import requests

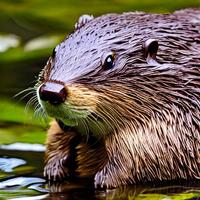
>>> # image of a beaver
>>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/beaver.png"
>>> image = Image.open(requests.get(url, stream=True).raw)
>>> display(downscale_images(image))
搜索相似图像:
img_embedding = (
    model.get_image_features(**processor([image], return_tensors="pt", truncation=True).to("cuda"))[0]
    .detach()
    .cpu()
    .numpy()
)
scores, retrieved_examples = ds_with_embeddings.get_nearest_examples("image_embeddings", img_embedding, k=1)
显示与海狸图像最相似的图片:
>>> images = [downscale_images(image) for image in retrieved_examples["image"]]
>>> # see the closest text and image
>>> print(retrieved_examples["image_description"])
>>> display(images[0])
['Salmon swim upstream but they see a grizzly bear and are in shock. The bear has a smug look on his face when he sees the salmon.']
描述的意思是:鲑鱼正逆流而上,看到一只灰熊后大吃一惊;灰熊看着鲑鱼,露出得意的表情。
保存、上传和加载嵌入
可以使用 save_faiss_index 保存数据集的嵌入索引:
ds_with_embeddings.save_faiss_index("embeddings", "embeddings/embeddings.faiss")ds_with_embeddings.save_faiss_index("image_embeddings", "embeddings/image_embeddings.faiss")将嵌入存储在数据集仓库中是一种好习惯。下面创建仓库,将嵌入上传,以便日后拉取。
先登录 Hugging Face Hub,创建数据集仓库并上传索引,再通过 snapshot_download 下载加载:
from huggingface_hub import HfApi, notebook_login, snapshot_download

notebook_login()
from huggingface_hub import HfApi
api = HfApi()
api.create_repo("merve/faiss_embeddings", repo_type="dataset")
api.upload_folder(
folder_path="./embeddings",
repo_id="merve/faiss_embeddings",
repo_type="dataset",
)snapshot_download(repo_id="merve/faiss_embeddings", repo_type="dataset", local_dir="downloaded_embeddings")通过 load_faiss_index,可以将嵌入索引加载到尚未包含嵌入的数据集上:
ds = ds["train"]
ds.load_faiss_index("embeddings", "./downloaded_embeddings/embeddings.faiss")
# infer again
prmt = "people under the rain"
prmt_embedding = (
model.get_text_features(**tokenizer([prmt], return_tensors="pt", truncation=True).to("cuda"))[0]
.detach()
.cpu()
.numpy()
)
scores, retrieved_examples = ds.get_nearest_examples("embeddings", prmt_embedding, k=1)>>> display(retrieved_examples["image"][0])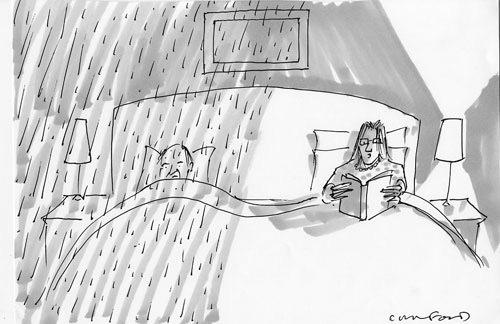
原文:Embedding multimodal data for similarity search using 🤗 transformers, 🤗 datasets and FAISS。作者/维护方:Merve Noyan / Hugging Face Cookbook。本文为中文翻译,代码及命令保留原文。











暂无评论内容