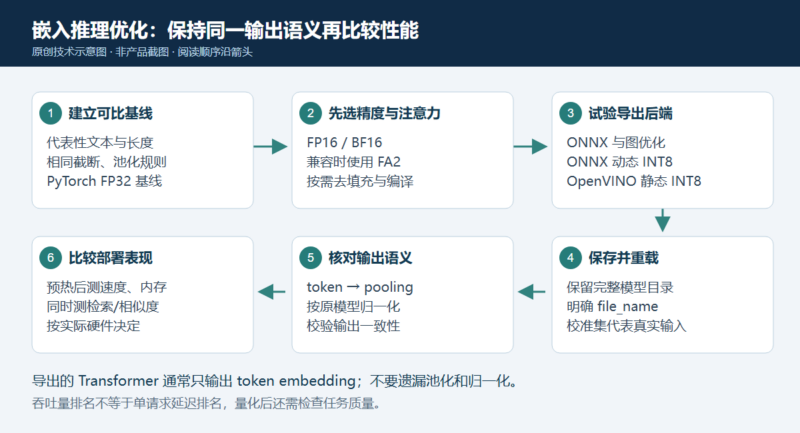



原文:Speeding up Inference;作者:Sentence Transformers 文档贡献者(页面无个人署名)。中文全文译写与编者审核:未完纪。核对日期:2026-10-05。
依据 2026-10-05 读取的滚动文档。文中 llama.cpp 对照使用 Sentence Transformers 6.1.0.dev0(084d9f7183b7)、PyTorch 2.11.0+cu128、Transformers 5.14.1、kernels 0.15.2 与 llama.cpp 4d91760;这是原文实验环境,不是对稳定发行版本或当前安装环境的承诺。
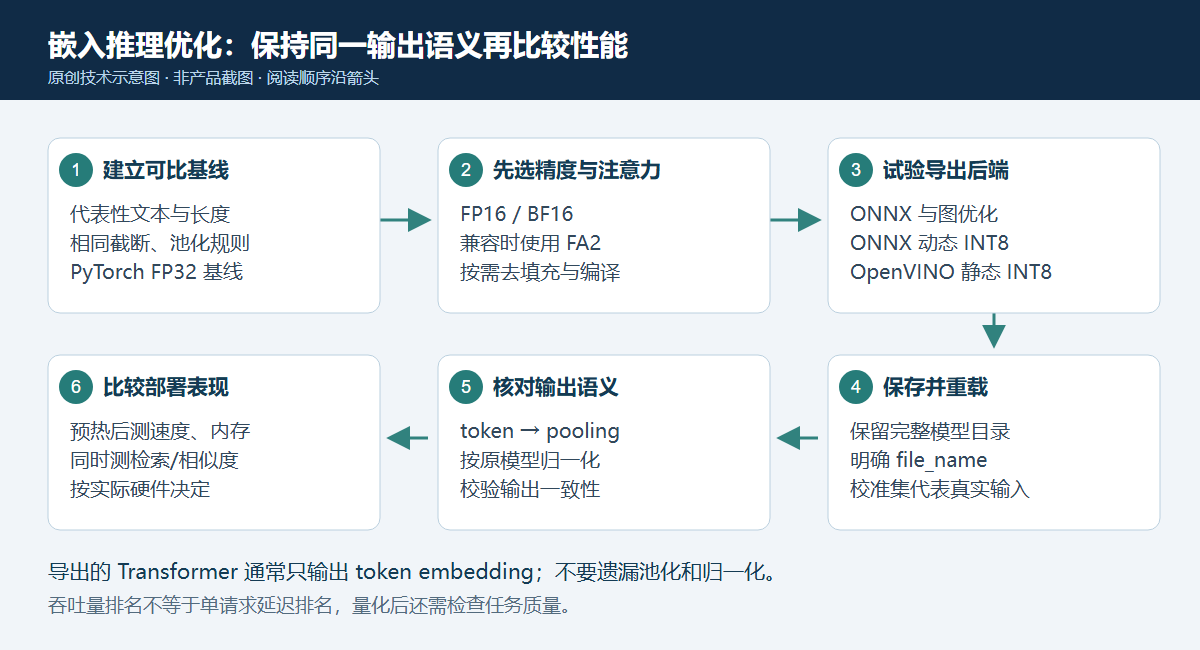
本篇讨论后端层面的加速:计算精度、注意力实现、编译、ONNX、OpenVINO 和模型权重量化。它们与输出向量的二值/标量压缩、Matryoshka 可截断嵌入、无注意力的静态嵌入模型属于互补手段。后者主要改变向量存储、检索成本或模型结构,不能直接与某个运行后端的吞吐量倍数混为一谈。
Sentence Transformers 支持三种主要嵌入计算后端:默认 PyTorch、使用 ONNX Runtime 的 ONNX,以及主要面向 Intel 硬件优化的 OpenVINO。应先保留可比的模型与输出语义,再选择优化路径。
一、PyTorch:从默认配置开始
不指定后端时使用 PyTorch;未指定 device 时,会在 cuda、mps 与 cpu 中选择可用的较强设备。基础用法如下:
默认PyTorch后端
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2")

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
float16 与 bfloat16
PyTorch 默认使用 float32。GPU 上可以尝试 float16,把浮点精度减半,通常能减少计算与显存成本,但仍需检查精度变化。初始化时通过 model_kwargs 指定 torch_dtype,或在加载后调用 model.half()。
FP16:初始化指定类型或调用half
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", model_kwargs={"torch_dtype": "float16"})
# or: model.half()

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
bfloat16 同样属于低精度格式,原文指出它通常更能保留 FP32 的准确性表现。可以指定 torch_dtype='bfloat16',或调用 model.bfloat16()。实际支持和收益依硬件及模型而定。
BF16:另一种低精度选择
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", model_kwargs={"torch_dtype": "bfloat16"})
# or: model.bfloat16()

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
Flash Attention 与自动去填充
Flash Attention 是更高效的注意力实现。当模型架构兼容、且安装了支持变长序列的实现时,Sentence Transformers 可以把纯文本输入拼为一个序列,跳过把每条短文本补到当前批次最长长度的 padding。文本长度差异大时,省掉的无效计算尤其明显。
在 model_kwargs 中设置 attn_implementation='flash_attention_2'。原文提供两条安装路线:pip install kernels 可提供支持而无需单独安装 flash-attn;也可使用 pip install flash-attn。安装仍需满足对应平台、GPU和版本兼容要求。
使用FA2与BF16
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    model_kwargs={"attn_implementation": "flash_attention_2", "torch_dtype": "bfloat16"},
)

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
自动 unpadding 要求 transformers >= 5.0.0,并在变长 Flash Attention 与模型架构兼容时默认启用。可以在底层 Transformer 模块上手动控制:False 强制填充,True 明确请求去填充,None 自动检测。
控制底层Transformer的unpad_inputs
model[0].unpad_inputs = False   # Force padding (e.g. for architectures that don't support unpadded inputs)
model[0].unpad_inputs = True    # Explicitly request unpadding
model[0].unpad_inputs = None    # Auto-detect (default)
原文用 BAAI/bge-base-en-v1.5,在四类不同文本长度的数据集上比较三种注意力配置,并对不同 batch size 的结果汇总。输入展平在该测试中提高吞吐、减少显存,最大收益来自长度混合的数据集,其文本为 10—500 tokens;效果仍取决于模型与批量。
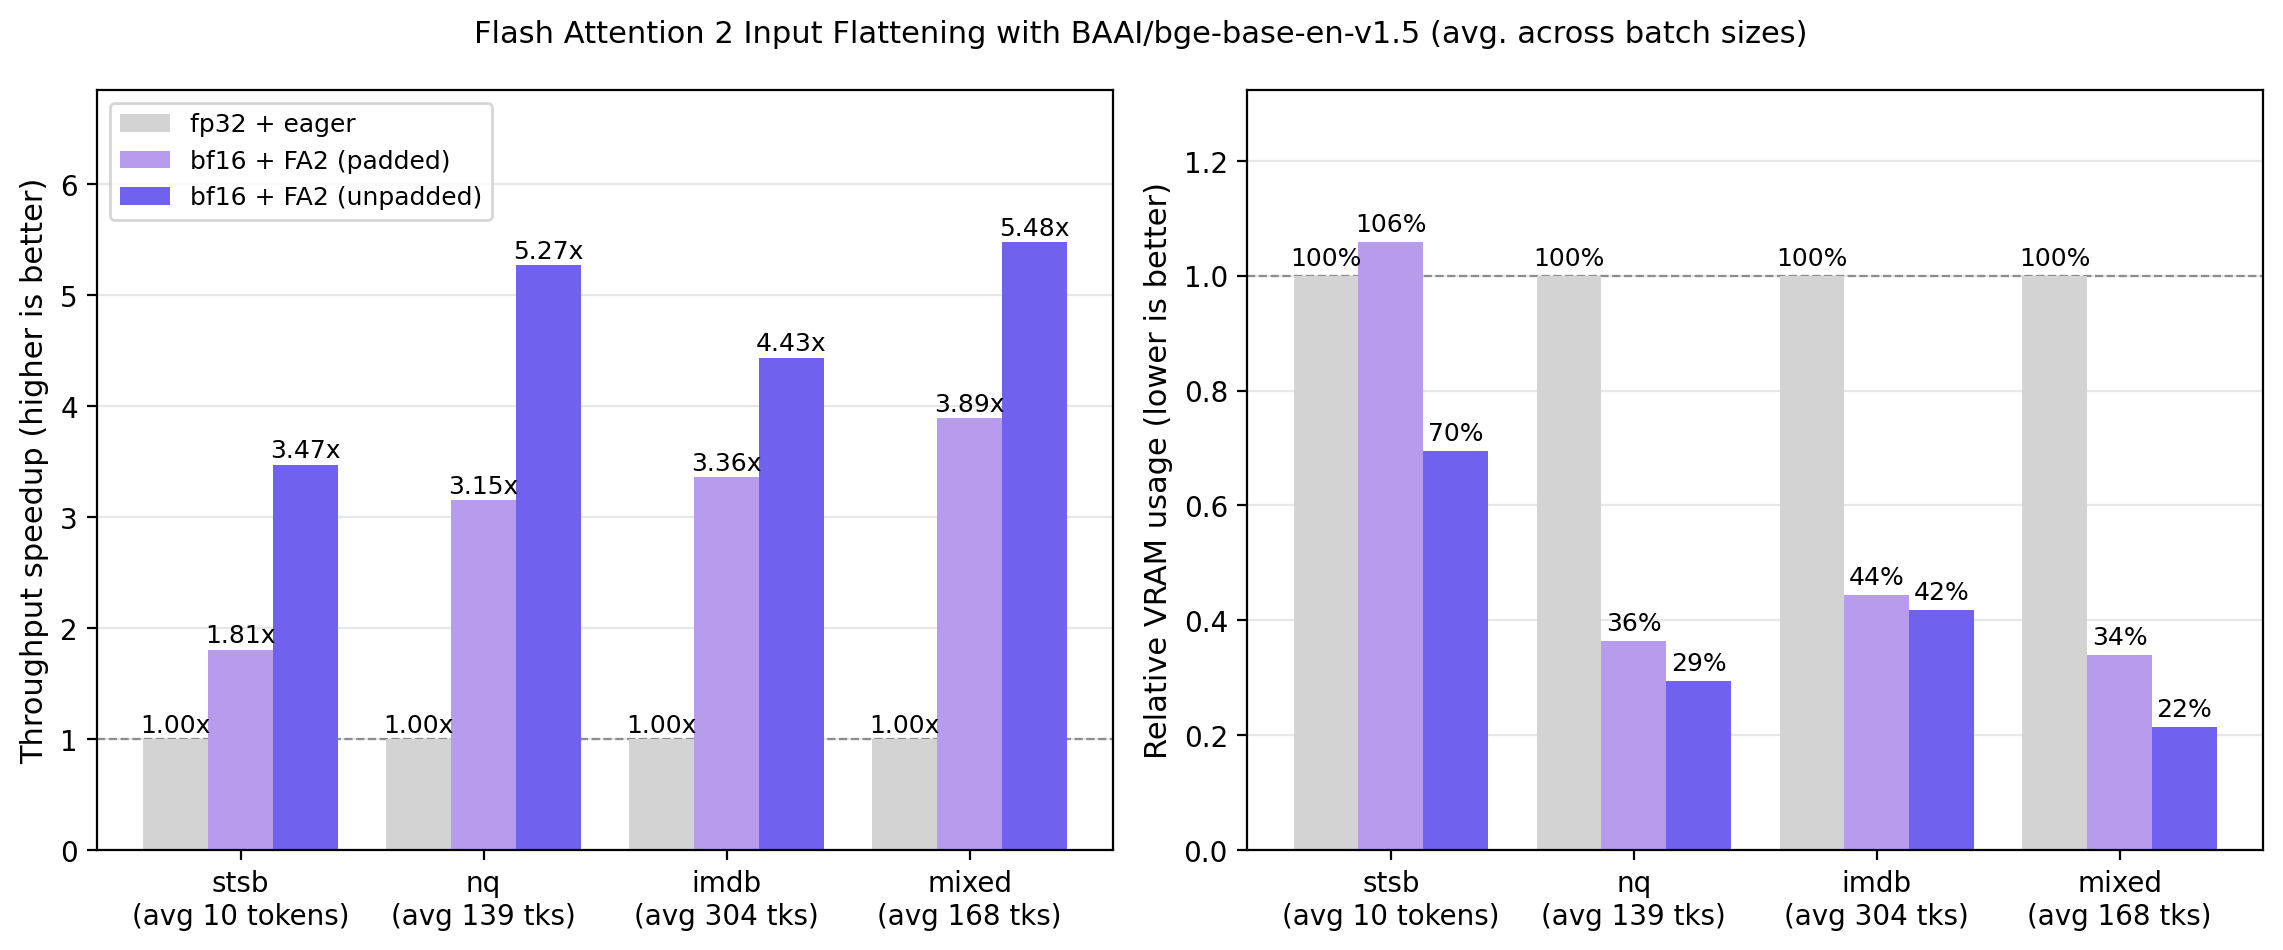
后文的后端测试也显示,FP16 结合 FA2 和自动去填充,在被测模型上的中位吞吐加速为 FP32 的 3.87 倍,平均任务质量未下降。这是该实验的汇总结果,不能推广成任何模型都会达到的性能。
输入展平也适用于训练。使用 CachedMultipleNegativesRankingLoss 这类梯度缓存损失时,可用 mini_batch_num_tokens 替代按序列条数计算的 mini_batch_size。小批次按总 token 数打包,使每批计算量与内存更可预测,不受文本长度分布那么明显的影响。
训练示例:按token预算划分小批次
from sentence_transformers import SentenceTransformer, losses

model = SentenceTransformer(
    "answerdotai/ModernBERT-base",
    model_kwargs={"attn_implementation": "flash_attention_2", "torch_dtype": "bfloat16"},
)
loss = losses.CachedMultipleNegativesRankingLoss(model, mini_batch_num_tokens=32768)
应选择能让 GPU 充分工作的最小预算。超过吞吐平台期后继续加大预算,通常收益有限;当显存逼近上限,驱动可能转用系统内存而不是立即报错,反而悄悄拖慢训练。更多注意力实现包括 flash_attention_3、sdpa 等,可查阅 Transformers Attention Interface。
torch.compile:别漏掉形状与预热成本
model.compile() 用 torch.compile() 包装模型 forward。收益很依赖模型和硬件;大模型通常更容易受益,快速 GPU 上的小模型则可能主要受分词与 Python 开销支配,编译后提升很小甚至略慢。它可与 FP16/BF16 组合,但必须在自己的输入上测量。
dynamic=True编译与可变长度输入
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", model_kwargs={"torch_dtype": "bfloat16"})
model.compile(dynamic=True)

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
dynamic=True 允许编译图处理动态形状,减少输入长度变化造成的重复编译。若追求减少逐个GPU kernel启动的开销,可以尝试 reduce-overhead,它利用 CUDA graphs,尤其针对 batch size 为 1 的推理启动开销。
以CUDA graphs降低调用开销
model.compile(mode="reduce-overhead")
CUDA graphs 为每种输入形状捕获一张图,因此需要稳定形状。编码时可把文本固定填充到接近典型输入长度的上限:
固定padding长度的encode调用
embeddings = model.encode(sentences, processing_kwargs={"text": {"padding": "max_length", "max_length": 256}})
max_length 同时决定短文本补齐到哪里,以及长文本截断到哪里;省略时默认采用 tokenizer.model_max_length。若模型默认上限是8192,而真实文本很短,仍补到8192会让每次调用都处理巨大长度,可能比不编译更慢。CUDA graphs 还会复用输出缓冲:跨调用保留GPU tensor时应复制;默认 convert_to_numpy=True 已把结果拷回CPU,避免这一问题。编译是惰性的,基准或正式服务之前应使用代表性输入预热。
若嵌入模型与生成式大语言模型共用 GPU,要同时观察显存和生成延迟,两者可能竞争算力。对延迟敏感的本地应用,把小嵌入模型移到 CPU 有时更合适,可在构造模型时指定 device='cpu',或在 encode 中指定。
二、ONNX:导出、选择运行提供器与持久化
ONNX 后端把模型转换为 ONNX 格式,再由 ONNX Runtime 执行。GPU或CPU加速分别使用 onnx-gpu、onnx 安装附加项。
安装ONNX后端依赖
pip install sentence-transformers[onnx-gpu]
# or
pip install sentence-transformers[onnx]
构造模型时指定 backend='onnx'。如果模型目录或仓库已经带有 ONNX 文件,库会直接使用;否则自动转换。
加载或首次导出ONNX模型
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="onnx")

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
导出只转换 Transformer 组件,它输出的是 token embedding,而不是最终 sentence embedding。若离开 Sentence Transformers 独立使用 ONNX,必须复现原模型的池化(如 mean pooling)以及原先使用的归一化;否则得到的向量与原模型语义可能不同。
model_kwargs 会传递给 ORTModel.from_pretrained,几个重要参数如下。
| 参数 | 含义 |
|---|---|
| provider | 选择ONNX Runtime execution provider,例如CPUExecutionProvider。未指定时使用可用的较强提供器,例如CUDAExecutionProvider。 |
| file_name | 选取ONNX文件,默认model.onnx或onnx/model.onnx;加载优化、量化产物时尤其重要。 |
| export | 是否导出;未指定且仓库/目录没有ONNX模型时,自动设为True。 |
| session_options | onnxruntime.SessionOptions实例,可调整intra_op_num_threads等,以匹配CPU和工作负载。 |
为了避免每次启动重复导出,应保存转换结果。本地模型调用 save_pretrained;来自 Hub 的模型可以推送到对应仓库,示例使用 create_pr=True 创建待审查改动。
本地保存ONNX结果
model = SentenceTransformer("path/to/my/model", backend="onnx")
model.save_pretrained("path/to/my/model")
向Hub提交转换结果的原文示例
model = SentenceTransformer("intfloat/multilingual-e5-small", backend="onnx")
model.push_to_hub("intfloat/multilingual-e5-small", create_pr=True)
优化ONNX模型
Optimum 可以优化 ONNX 图,适用于CPU与GPU。export_optimized_onnx_model 将结果写入指定目录或模型仓库。model 必须已通过 ONNX 后端加载,可以是 Sentence Transformer、Sparse Encoder 或 Cross Encoder;optimization_config 接受 O1、O2、O3、O4,或 OptimizationConfig 实例。
model_name_or_path 指定本地输出路径或 Hub 仓库;push_to_hub 决定是否推送;create_pr 决定以PR形式提交;file_suffix 可自定义保存文件的后缀,默认使用优化等级名称,若配置不是等级字符串则使用 optimized。下面保留原文 O3 的完整流程;O3 包含基础和扩展通用优化、Transformer特定融合以及快速GELU近似。
Hub模型:仅需执行一次的O3优化
from sentence_transformers import SentenceTransformer, export_optimized_onnx_model

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="onnx")
export_optimized_onnx_model(
    model=model,
    optimization_config="O3",
    model_name_or_path="sentence-transformers/all-MiniLM-L6-v2",
    push_to_hub=True,
    create_pr=True,
)
PR合并前:从refs/pr加载优化文件
from sentence_transformers import SentenceTransformer

pull_request_nr = 2 # NOTE: Update this to the number of your pull request
model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_O3.onnx"},
    revision=f"refs/pr/{pull_request_nr}"
)
PR合并后:直接选择优化后的ONNX文件
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_O3.onnx"},
)
本地模型使用同一函数写入目录,然后通过 file_name 指向优化产物:
本地模型:导出优化文件
from sentence_transformers import SentenceTransformer, export_optimized_onnx_model

model = SentenceTransformer("path/to/my/mpnet-legal-finetuned", backend="onnx")
export_optimized_onnx_model(
    model=model, optimization_config="O3", model_name_or_path="path/to/my/mpnet-legal-finetuned"
)
本地模型:重载O3文件
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "path/to/my/mpnet-legal-finetuned",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_O3.onnx"},
)
动态量化ONNX模型
使用 Optimum 可把模型量化为 INT8,以加速 CPU 推理。export_dynamic_quantized_onnx_model 采用动态量化,与静态量化不同,不需要校准数据集。model 必须已加载为ONNX后端;quantization_config 可为 arm64、avx2、avx512、avx512_vnni,或 QuantizationConfig 实例。
其余参数同样包括 model_name_or_path、push_to_hub、create_pr 和 file_suffix。原文参数说明写默认后缀 qint8_quantized,而其按硬件配置的示例加载 model_qint8_avx512_vnni.onnx;使用时应确认实际产物名,不要凭默认描述猜测。作者在自己的CPU上观察到这些默认配置带来大致相当的加速,不能据此推断所有CPU均等。
Hub模型:按avx512_vnni进行一次动态INT8量化
from sentence_transformers import SentenceTransformer, export_dynamic_quantized_onnx_model

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="onnx")
export_dynamic_quantized_onnx_model(
    model=model,
    quantization_config="avx512_vnni",
    model_name_or_path="sentence-transformers/all-MiniLM-L6-v2",
    push_to_hub=True,
    create_pr=True,
)
PR合并前:加载量化文件
from sentence_transformers import SentenceTransformer

pull_request_nr = 2 # NOTE: Update this to the number of your pull request
model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
    revision=f"refs/pr/{pull_request_nr}",
)
PR合并后:加载量化文件
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
)
本地模型:动态量化
from sentence_transformers import SentenceTransformer, export_dynamic_quantized_onnx_model

model = SentenceTransformer("path/to/my/mpnet-legal-finetuned", backend="onnx")
export_dynamic_quantized_onnx_model(
    model=model, quantization_config="avx512_vnni", model_name_or_path="path/to/my/mpnet-legal-finetuned"
)
本地模型:重载INT8结果
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "path/to/my/mpnet-legal-finetuned",
    backend="onnx",
    model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
)
三、OpenVINO:导出与静态量化
OpenVINO通过自己的模型格式加速CPU推理。安装对应附加项后,构造模型时使用 backend='openvino';已有该格式就直接加载,否则自动转换。
安装OpenVINO依赖
pip install sentence-transformers[openvino]
加载或导出OpenVINO模型
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="openvino")

sentences = ["This is an example sentence", "Each sentence is converted"]
embeddings = model.encode(sentences)
与ONNX一样,独立运行OpenVINO导出文件时,需要自行完成适当的池化与归一化,因为导出的是输出token embedding的Transformer组件。model_kwargs 传递给 OVBaseModel.from_pretrained。file_name 默认是 openvino_model.xml 或 openvino/openvino_model.xml;export 未指定且没有现成OpenVINO模型时会自动为True。原文在解释 file_name 时误称其为ONNX文件,本篇按实际.xml格式纠正术语。
同样应保存转换结果,避免每次重导出。下列分别是本地保存与向Hub创建PR的示例。
本地持久化OpenVINO模型
model = SentenceTransformer("path/to/my/model", backend="openvino")
model.save_pretrained("path/to/my/model")
向Hub提交OpenVINO结果的原文示例
model = SentenceTransformer("intfloat/multilingual-e5-small", backend="openvino")
model.push_to_hub("intfloat/multilingual-e5-small", create_pr=True)
OpenVINO的INT8训练后静态量化
Optimum Intel 可将OpenVINO模型量化为INT8。export_static_quantized_openvino_model 将结果保存到目录或仓库,静态量化需要校准样本。参数如下:
| 参数 | 意义 |
|---|---|
| model | 以OpenVINO后端加载的Sentence Transformer、Sparse Encoder或Cross Encoder。 |
| quantization_config | 可选;None使用默认8位量化,也接受配置字典或OVQuantizationConfig实例。 |
| model_name_or_path | 本地输出目录或Hub仓库。 |
| dataset_name | 校准数据集;未指定时默认使用glue数据集的sst2子集。 |
| dataset_config_name | 校准数据集的具体配置。 |
| dataset_split | 使用的数据分区,如train或test。 |
| column_name | 用于校准的文本列。 |
| push_to_hub / create_pr | 决定推送及是否以PR方式提交。 |
| file_suffix | 输出文件后缀,默认qint8_quantized。 |
Hub模型:一次静态INT8量化
from sentence_transformers import SentenceTransformer, export_static_quantized_openvino_model

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2", backend="openvino")
export_static_quantized_openvino_model(
    model=model,
    quantization_config=None,
    model_name_or_path="sentence-transformers/all-MiniLM-L6-v2",
    push_to_hub=True,
    create_pr=True,
)
PR合并前:从PR重载OpenVINO量化结果
from sentence_transformers import SentenceTransformer

pull_request_nr = 2 # NOTE: Update this to the number of your pull request
model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="openvino",
    model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
    revision=f"refs/pr/{pull_request_nr}"
)
PR合并后:重载量化结果
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "sentence-transformers/all-MiniLM-L6-v2",
    backend="openvino",
    model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
)
本地模型:显式使用OVQuantizationConfig
from sentence_transformers import SentenceTransformer, export_static_quantized_openvino_model
from optimum.intel import OVQuantizationConfig

model = SentenceTransformer("path/to/my/mpnet-legal-finetuned", backend="openvino")
quantization_config = OVQuantizationConfig()
export_static_quantized_openvino_model(
    model=model, quantization_config=quantization_config, model_name_or_path="path/to/my/mpnet-legal-finetuned"
)
本地模型:加载量化后的XML文件
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "path/to/my/mpnet-legal-finetuned",
    backend="openvino",
    model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
)
四、如何阅读原文后端基准
最佳后端取决于硬件、模型和输入长度。主要GPU/CPU汇总图以对应模型、对应工作负载的PyTorch FP32为基线,同时展示中位加速比和平均任务质量比例。误差线表示被测组合之间的差异,不是置信区间;GPU llama.cpp 结果使用其匹配的FP32基线。以下完整保留实验条件。
硬件、数据集与模型
GPU为RTX 3090,CPU为i7-13700K。数据集从短句到长评论:sentence-transformers/stsb 平均38.9字符、标准差13.9;sentence-transformers/natural-questions仅取答案,平均619.6字符、标准差345.3;stanfordnlp/imdb把文本重复4次,平均9589.3字符、标准差633.4。
| 模型 | 规模与范围 |
|---|---|
| sentence-transformers/all-MiniLM-L6-v2 | 2270万参数 |
| BAAI/bge-base-en-v1.5 | 1.09亿参数 |
| mixedbread-ai/mxbai-embed-large-v1 | 3.35亿参数 |
| BAAI/bge-m3 | 5.67亿参数;仅GPU测试 |
GPU的Sentence Transformers和ONNX每个数据集使用2000个样本。CPU测试对MiniLM、BGE-base各用1000个样本,对mxbai-large用512个;mxbai-large只测短句和NQ答案,总共形成8个CPU模型/工作负载组合。每个后端取已测试的最佳batch size;CPU在8与20线程中选择较快者,ONNX Runtime显式设置intra-op线程,并把inter-op设为1。
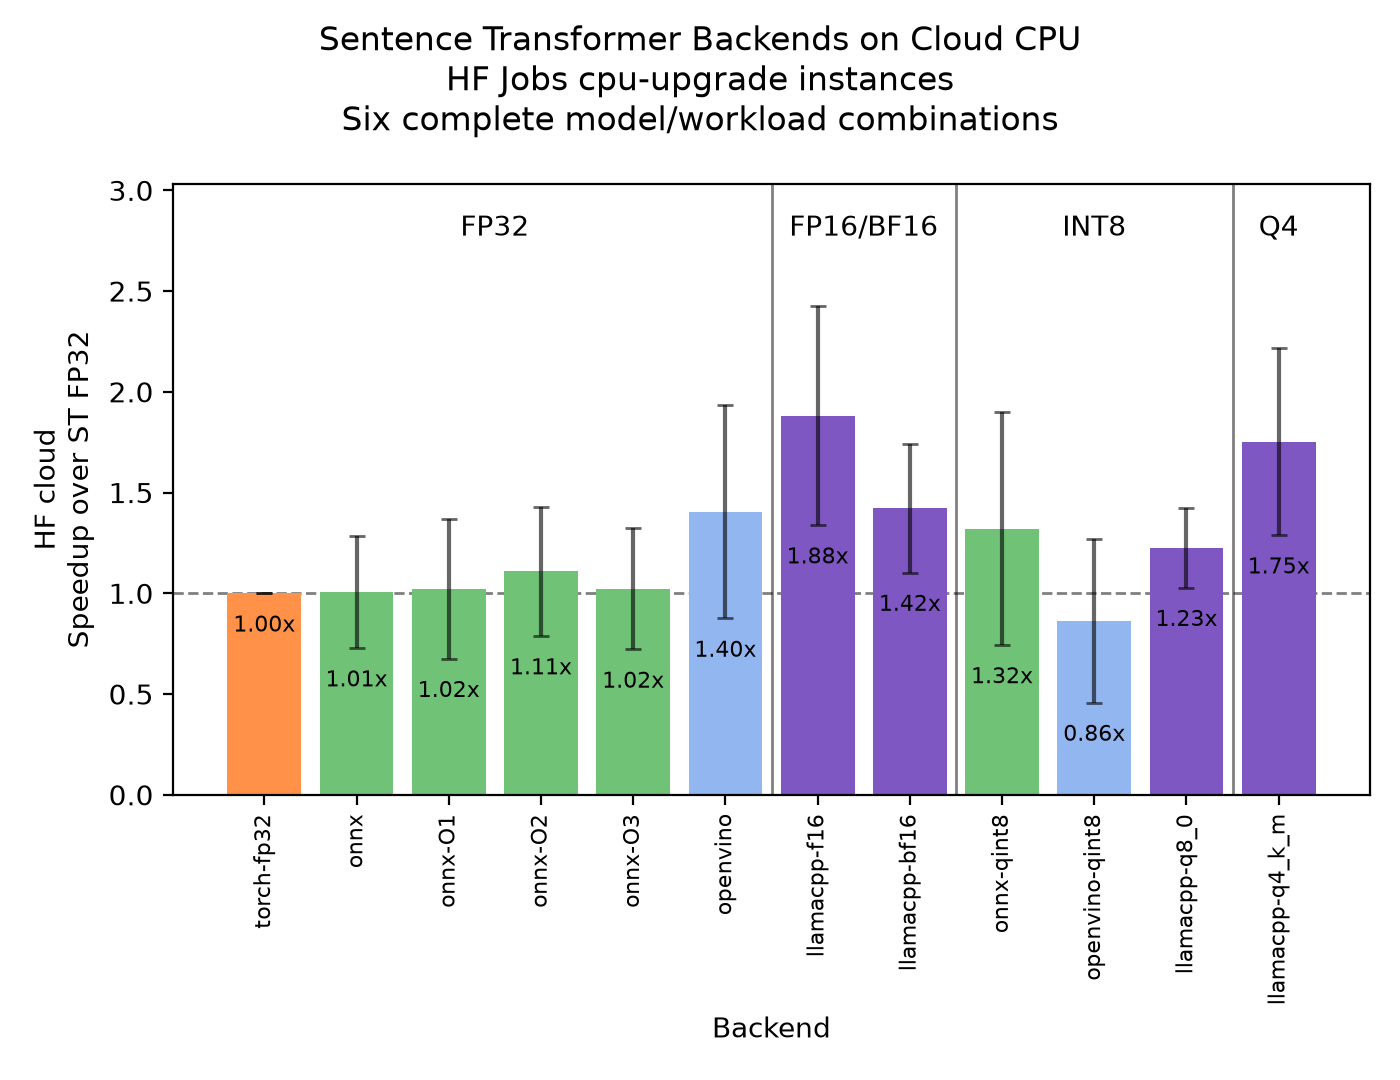
预热后,CPU计时采用五轮中位数或两轮平均值。CPU的torch-fp16、torch-bf16另用较小的128样本检查,沿用FP32选定的设置,计时两轮并与匹配FP32对照。Hugging Face Jobs cpu-upgrade实例上的排名与本地不同:云CPU测试中llama.cpp领先;其图包含6个模型/工作负载组合,基线是该CPU上的PyTorch FP32。
质量评估方法
每种配置的任务分数与FP32相比,先计算比例再平均。句子相似度使用STSB测试集、余弦相似度和Spearman秩相关,由EmbeddingSimilarityEvaluator评估;检索使用完整NanoBEIR集合、余弦相似度和NDCG@10,由InformationRetrievalEvaluator评估。
CPU质量条形图包括MiniLM、BGE-base、mxbai-large的两类任务,即每后端6个比例。质量评估使用匹配CPU或GPU的模型文件;OpenVINO及ONNX INT8在CPU上评估。CPU图中的torch-fp16/bf16质量条采用GPU得分与匹配GPU FP32的比例。GPU图中llama.cpp质量只评MiniLM和BGE-base,而吞吐还包含mxbai-large和BGE-M3;BGE-M3 Q4未通过与FP32的嵌入一致性检查,被排除。
图例中的后端名称
| 标签 | 配置含义 |
|---|---|
| torch-fp32 / torch-fp16 / torch-bf16 | PyTorch对应浮点精度。 |
| torch-fp16-fa2 / torch-bf16-fa2 | 对应低精度加FA2和自动去填充。 |
| onnx | ONNX FP32。 |
| onnx-O1 / O2 / O3 | ONNX FP32及对应图优化等级。 |
| onnx-O4 | ONNX FP16与O4优化。 |
| onnx-qint8 | avx512_vnni动态INT8量化;作者的默认硬件配置表现大致相当。 |
| openvino | 标准OpenVINO后端。 |
| openvino-qint8 | 使用OVQuantizationConfig的静态INT8量化。 |
| llamacpp-* | 原生llama.cpp运行GGUF,格式包括F16、BF16、Q8_0、Q4_K_M。 |
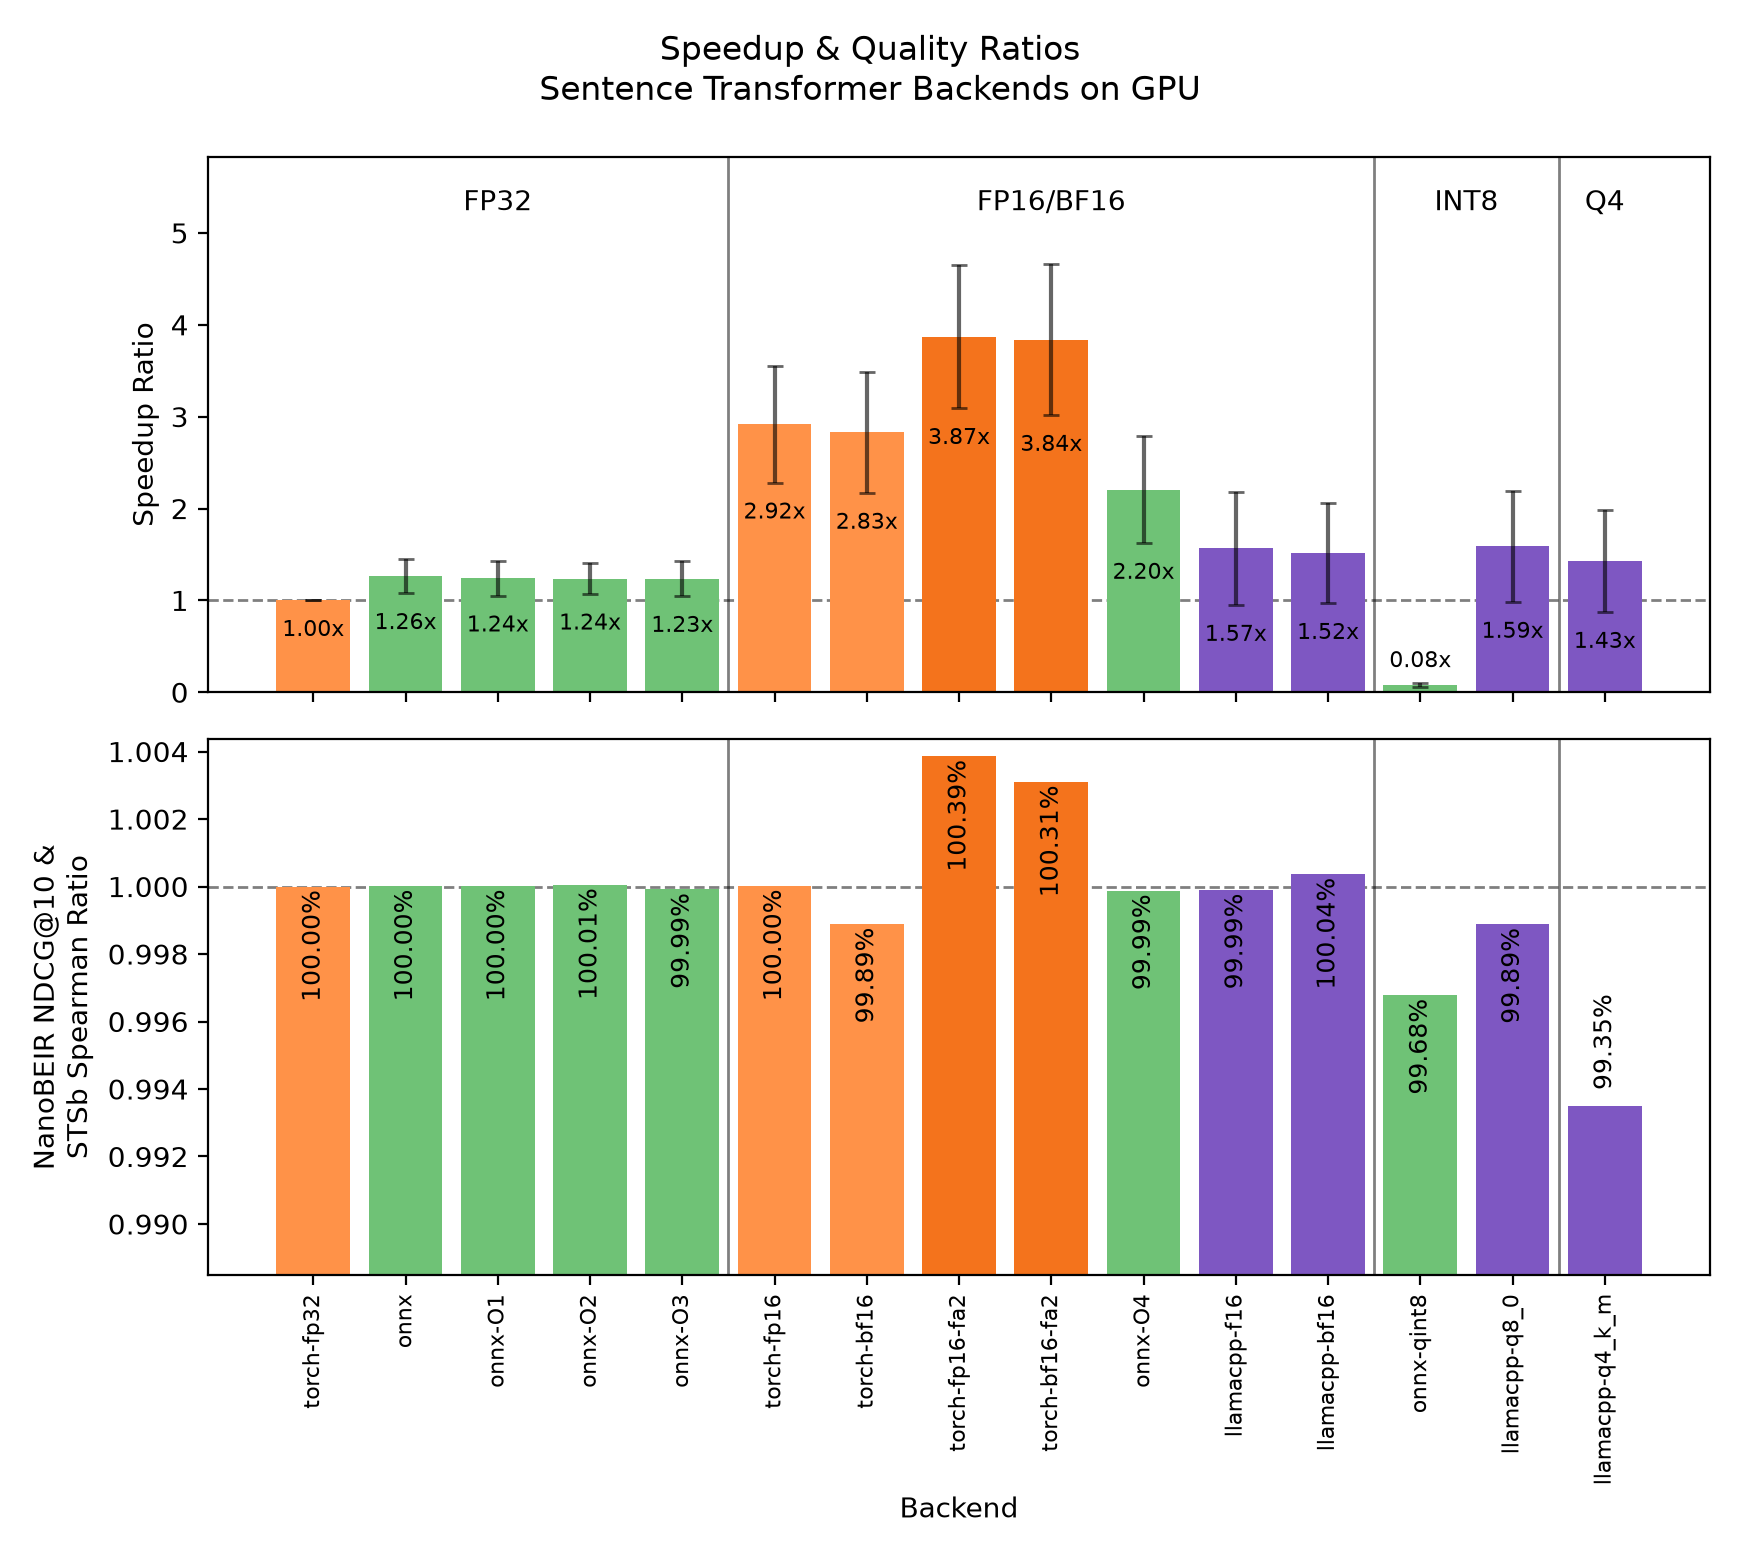
在这批GPU模型上,普通FP16的中位吞吐是FP32的2.92倍;结合FA2和去填充后为3.87倍,BF16的对应组合为3.84倍。因此,当模型支持时,低精度加Flash Attention是值得先测试的路线。
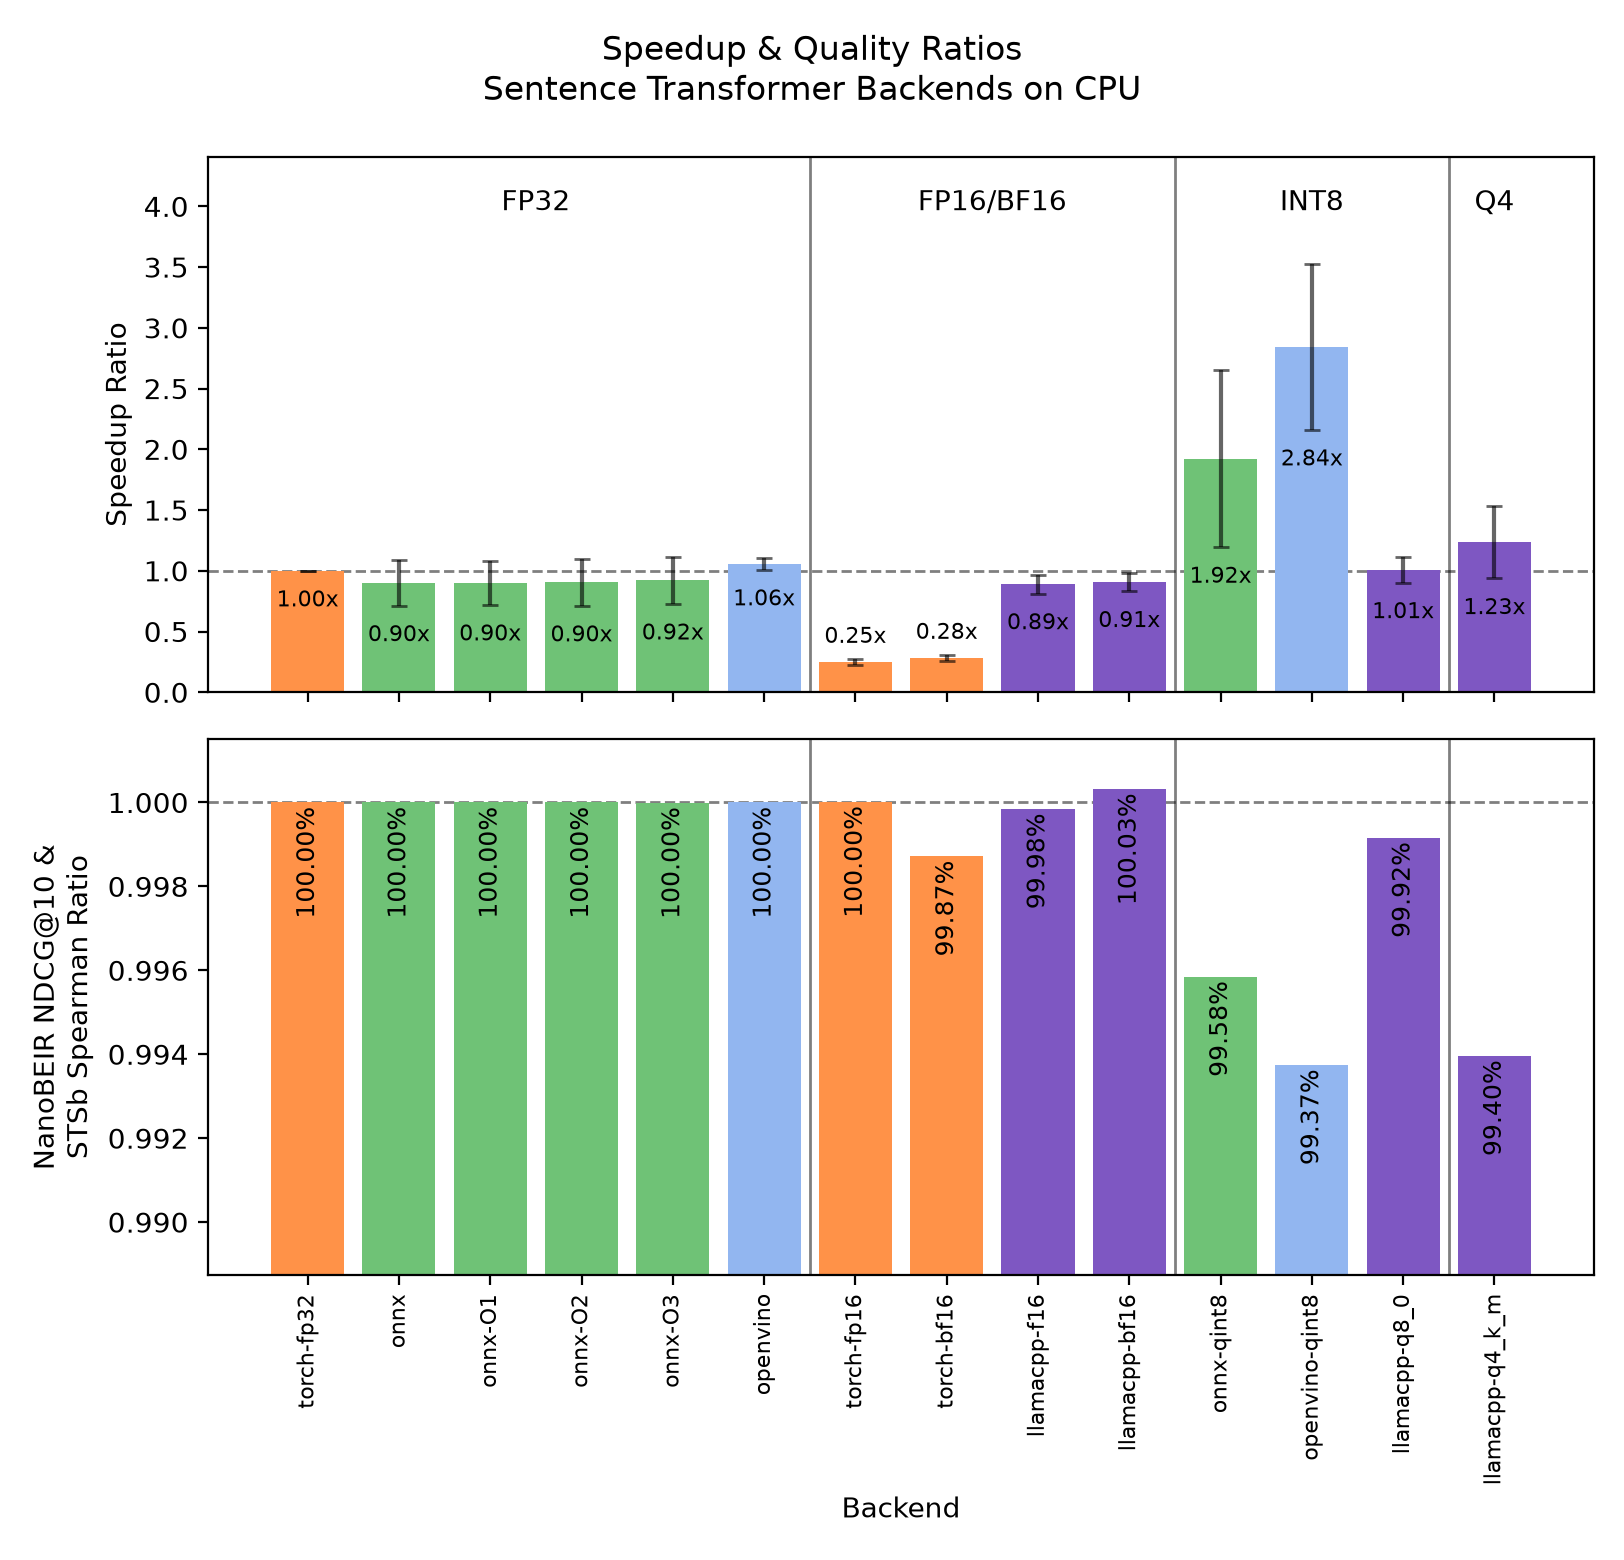
本地i7-13700K上OpenVINO INT8最佳,而作者的云实例上llama.cpp领先。Sentence Transformers在被测较小GPU模型上更强,8B模型上llama.cpp开始有竞争力。应以部署硬件和真实输入重新比较。
五、与原生 llama.cpp 比较到 8B 模型
前面的汇总最大到BGE-M3。原文另外比较到Qwen3-Embedding-8B,环境为WSL2上的24GB RTX 3090,两边都调优batch size。图展示吞吐中位数,误差线为重复测量的四分位间距。这与前面汇总图的组合间差异含义不同。
Sentence Transformers比较默认FA2去填充和开启padding;自动去填充仅适用于注意力实现和模型架构支持的纯文本输入。llama.cpp的GPU-table变体把默认放在CPU内存中的输入embedding table移到CUDA。
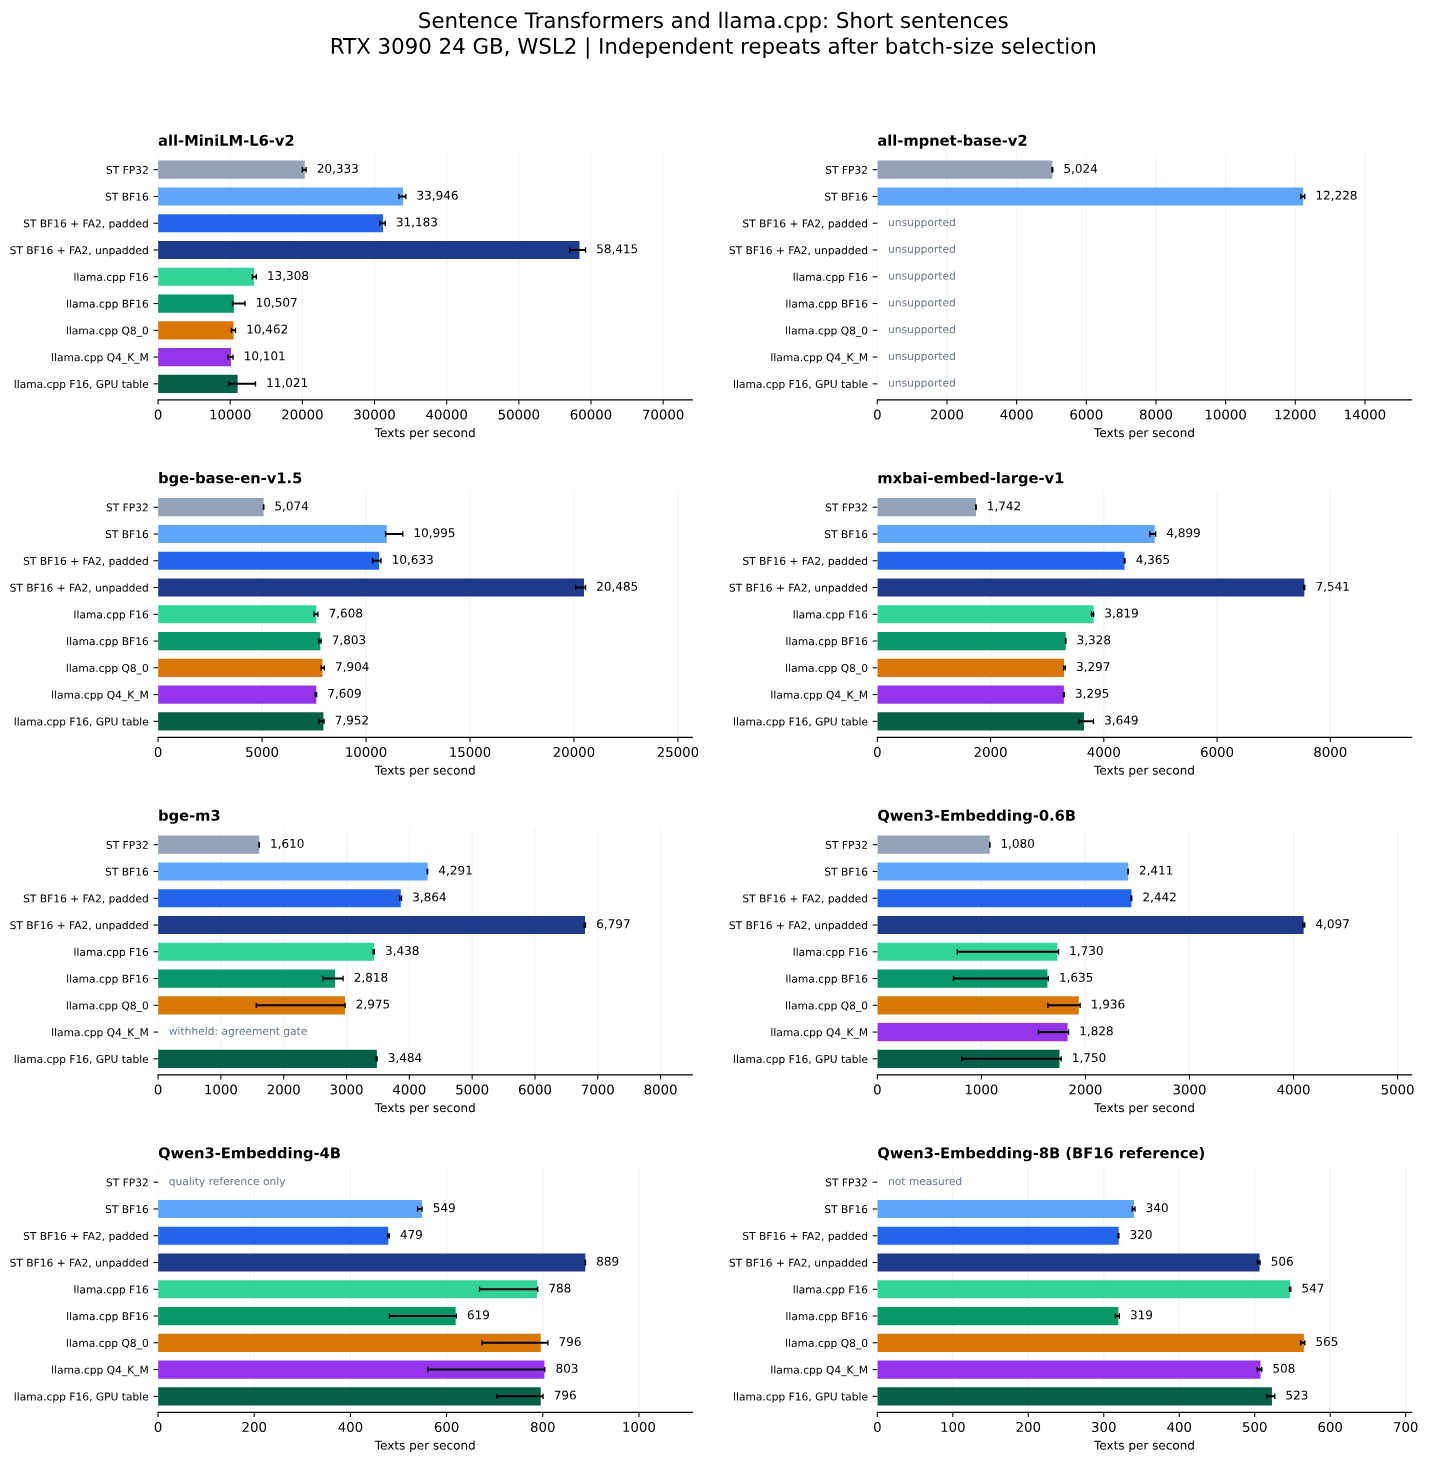
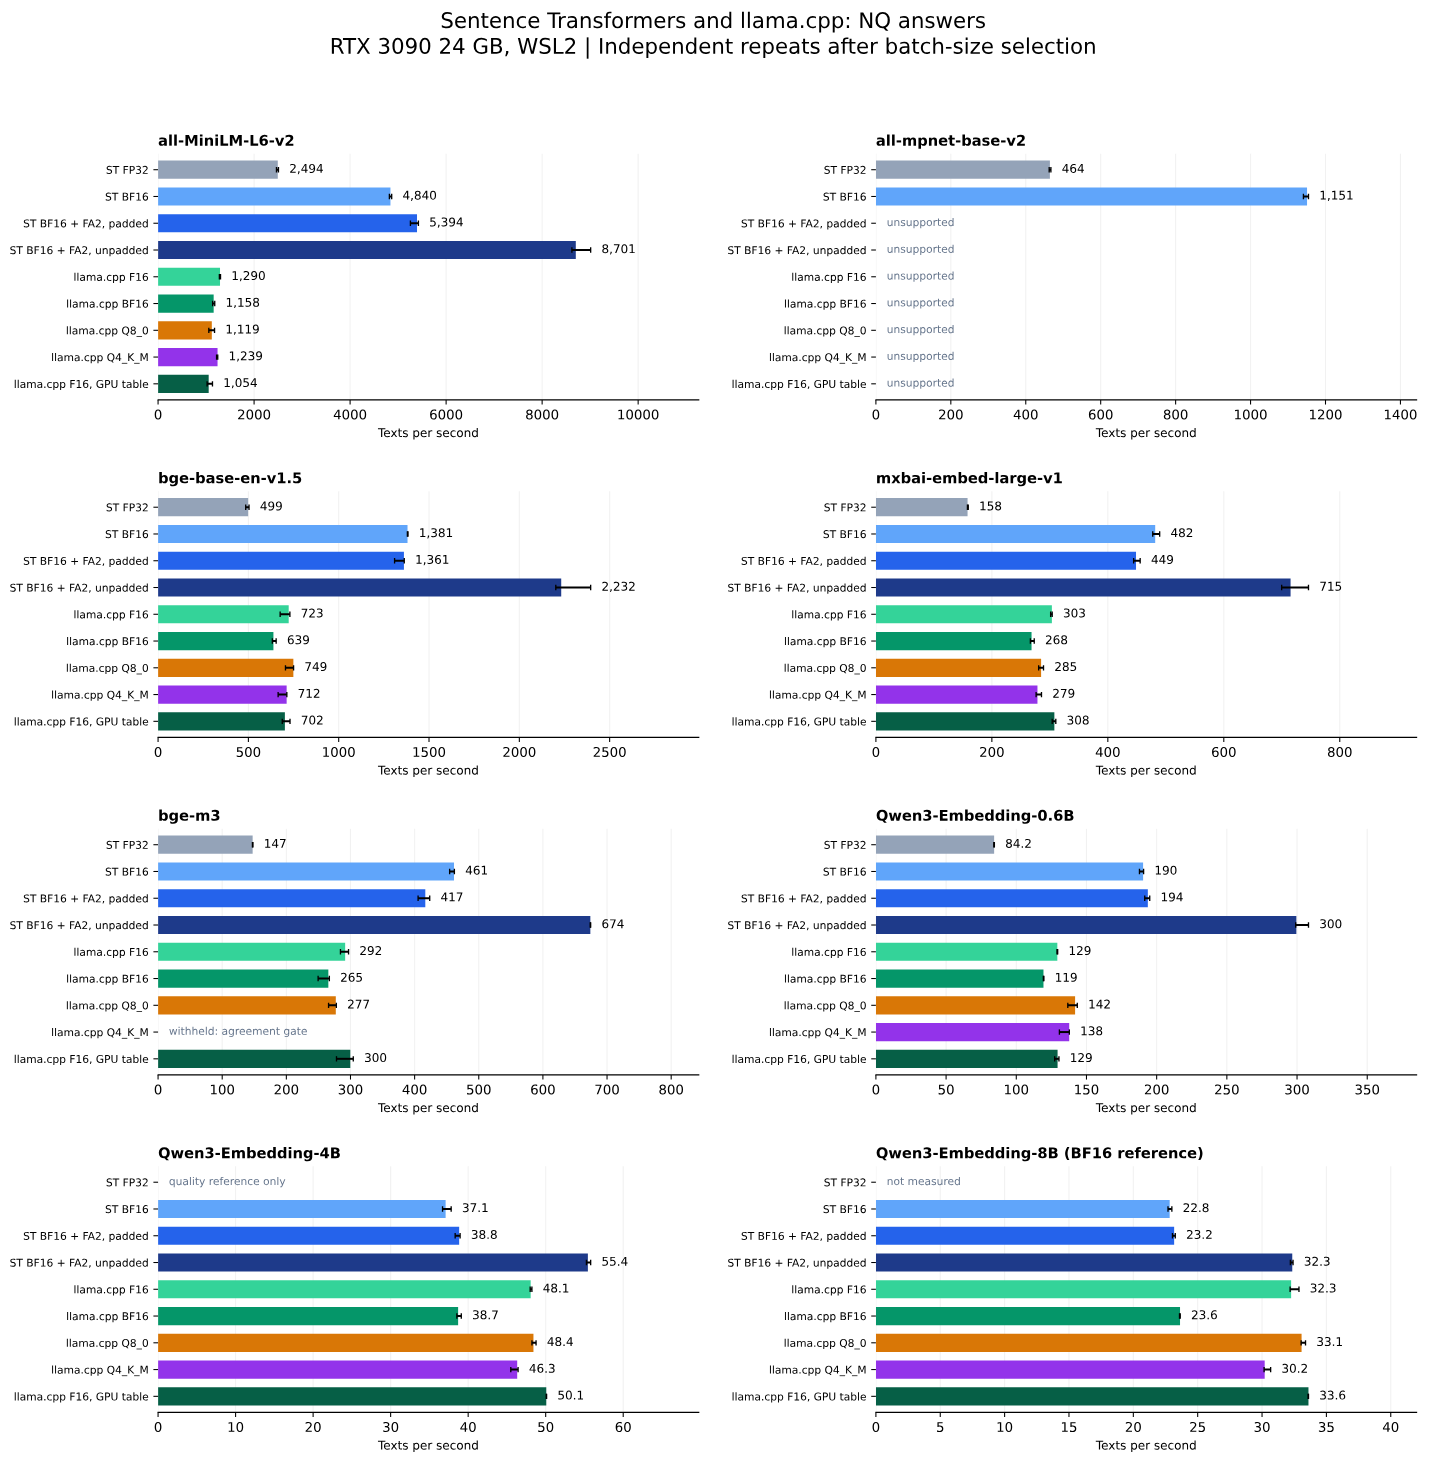
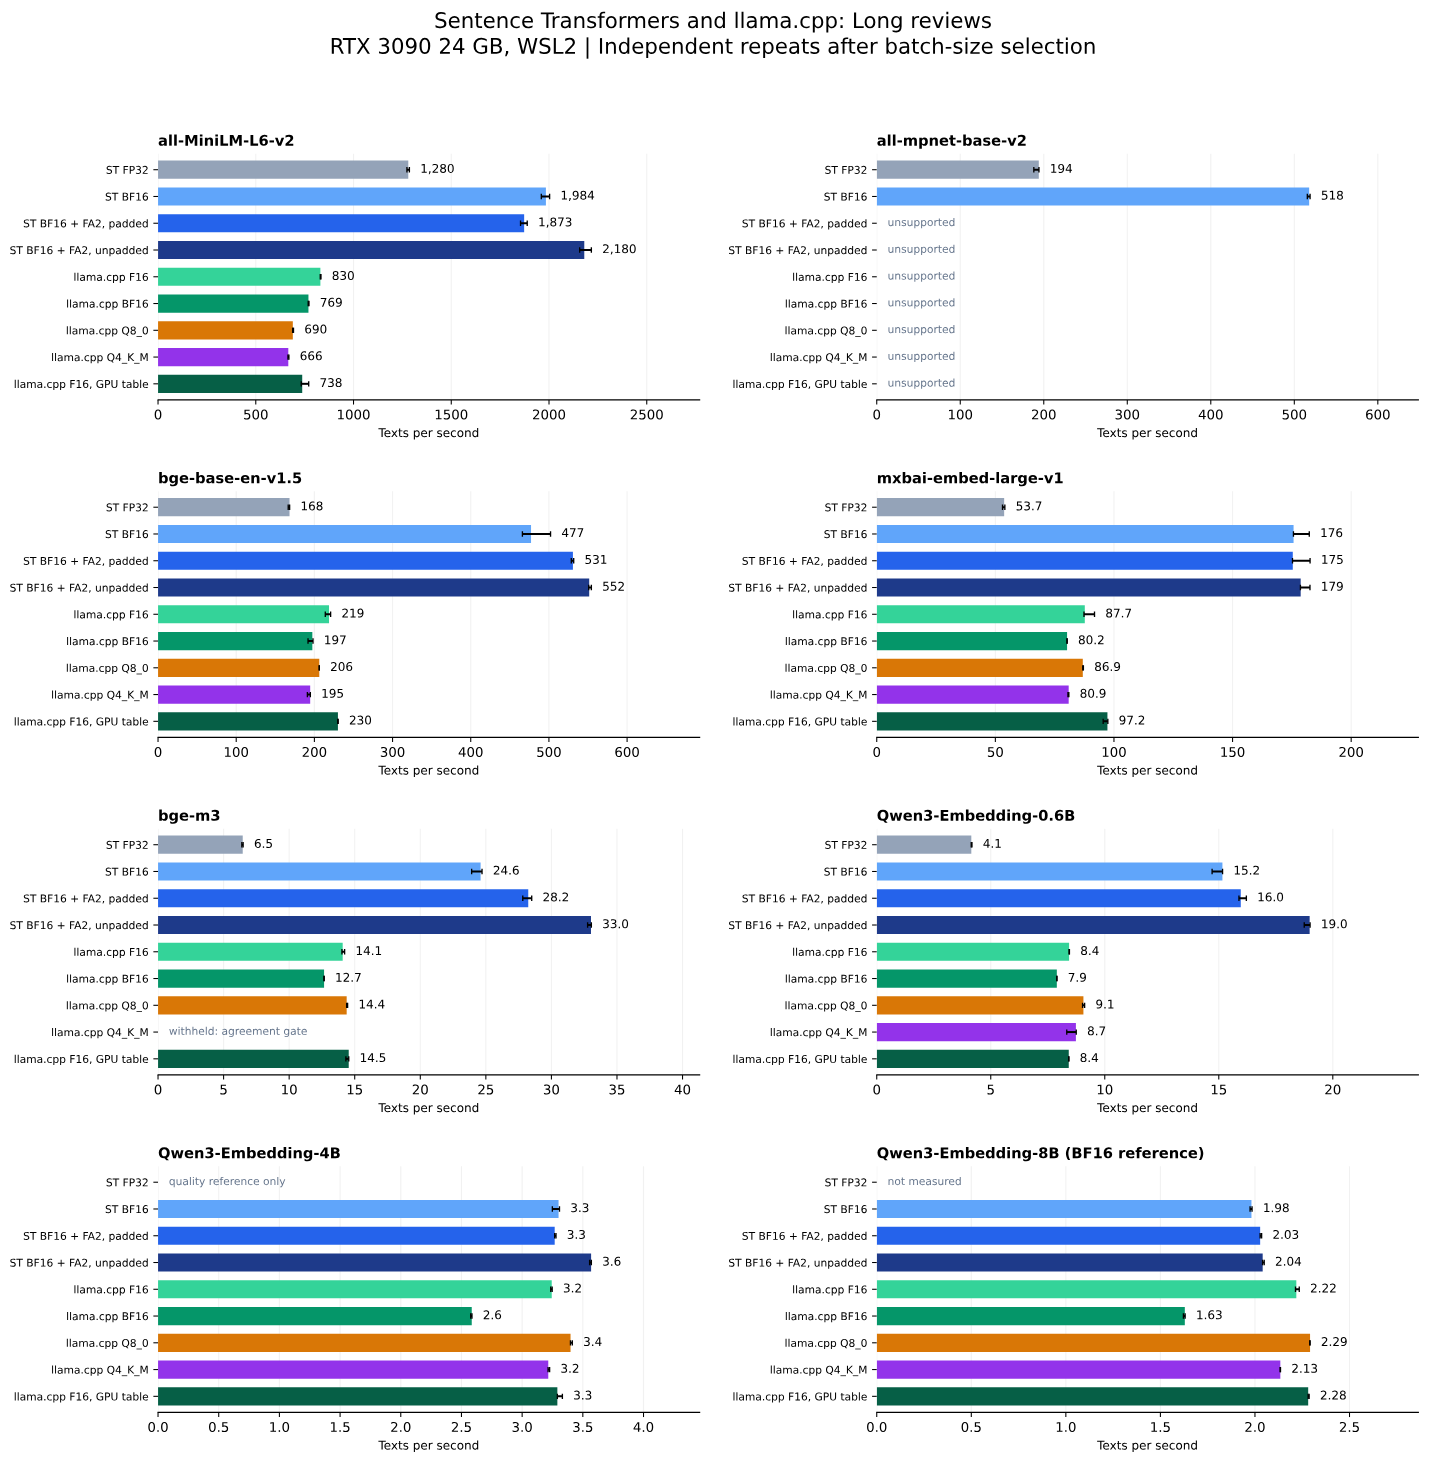
小模型上,Sentence Transformers的BF16+FA2+去填充领先:MiniLM为最快被测llama.cpp配置的2.6—6.7倍,BGE-base为2.4—3.0倍。Qwen3-Embedding-4B差距缩小,同一方案领先约5%—11%。
到Qwen3-Embedding-8B,llama.cpp的Q8_0、默认embedding table位置,在短句、NQ答案和长评论上分别快约12%、2%、12%。更激进的Q4没有继续提升,在三种负载上都比Q8慢。大模型尤其需要靠量化容纳进内存时,llama.cpp值得评估;本实验没有测试超过8B的模型。
这些都是调优批量后的吞吐量,最佳单请求延迟方案可能不同。本组比较只检查嵌入一致性,没有完整验证检索质量。两边计时均包含分词、模型执行、池化、归一化和把向量返回CPU内存;llama.cpp为直接调用,不包含HTTP传输。
为保证同负载比较,两边使用相同输入和截断上限:MiniLM 256、MPNet 384、BGE-base及mxbai-large 512、BGE-M3 8192、Qwen 0.6B 32768、Qwen 4B和8B 40960 tokens。工作负载为2000条短句、1000条NQ答案、256条长评论;Qwen 4B/8B使用其前1024、256、64条。
作者在552条文本上与FP32比较嵌入一致性,8B以BF16为参照。不通过者标为withheld,例如BGE-M3 Q4;被测版本的MPNet没有支持的FA2或llama.cpp实现,因此标为unsupported。两边使用相同检查点,GGUF测试F16、BF16、Q8_0和Q4_K_M。解码器模型设置 model[0].config.use_cache = False,避免嵌入推理保留生成缓存;llama.cpp GPU-table变体沿用默认F16的token预算。
该对照的软件版本为Sentence Transformers 6.1.0.dev0(084d9f7183b7)、PyTorch 2.11.0+cu128、Transformers 5.14.1、kernels 0.15.2,使用kernels-community/flash-attn2;llama.cpp修订为4d91760,并启用CUDA构建。复现实验时应保留这些版本差异。
六、选择后端的起点
原文决策流程可转换为以下测试顺序,而不是固定排名:GPU先考虑模型是否支持Flash Attention,支持时尝试FP16+Flash Attention,否则先测FP16;CPU若能接受小幅精度变化,先测OpenVINO INT8;若不能,则Intel CPU先测OpenVINO,其他CPU先测ONNX。原文也明确提醒,最终都应回到具体模型和数据比较。
这些建议还应结合前面的云CPU与8B对照理解:静态流程无法覆盖所有硬件和模型规模,不能排除其他后端。测速度时应同时记录模型版本、输入长度、batch size、线程、预热与输出语义,再检查实际检索或相似度质量。
七、图形化导出界面
Hugging Face Space sentence-transformers/backend-export 提供图形界面,可对ONNX或OpenVINO模型进行导出、优化和量化。它与前述代码接口是同一类工作的不同入口;使用第三方在线界面时,仍应核对模型与数据可否上传,以及生成文件的存储范围。
来源、署名与许可
原文与原始图版权归 Sentence Transformers 文档贡献者。源码仓库采用 Apache License 2.0,并保留 Copyright 2019 Nils Reimers 声明。本文为中文译写,编辑修改已明确标注;相关代码许可全文与署名在下文公开保留。第三方模型、数据集和后端仍适用各自许可证。
- 官方原文
- 原文仓库与Apache-2.0许可
- 导出/优化/量化界面
- ONNX Runtime执行提供器
- Transformers注意力接口
- 嵌入二值与标量量化
- Matryoshka嵌入模型
- Optimum
本文依据已获授权的原文进行中文全文译写;代码保留原有技术结构,英文标识符、代码注释和演示文本保留,编者补充已明确标注。原创流程图用于解释正文,不代表实测结果。
上游代码版权与完整许可
以下保留官方仓库完整 Apache License 2.0 及 Copyright 2019 Nils Reimers。中文翻译、静态审阅补充与原创流程图由未完纪于2026-10-05整理;原始基准图来自上述文档,未重新运行生成。
                                Apache License
                           Version 2.0, January 2004
                        http://www.apache.org/licenses/

   TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION

   1. Definitions.

      "License" shall mean the terms and conditions for use, reproduction,
      and distribution as defined by Sections 1 through 9 of this document.

      "Licensor" shall mean the copyright owner or entity authorized by
      the copyright owner that is granting the License.

      "Legal Entity" shall mean the union of the acting entity and all
      other entities that control, are controlled by, or are under common
      control with that entity. For the purposes of this definition,
      "control" means (i) the power, direct or indirect, to cause the
      direction or management of such entity, whether by contract or
      otherwise, or (ii) ownership of fifty percent (50%) or more of the
      outstanding shares, or (iii) beneficial ownership of such entity.

      "You" (or "Your") shall mean an individual or Legal Entity
      exercising permissions granted by this License.

      "Source" form shall mean the preferred form for making modifications,
      including but not limited to software source code, documentation
      source, and configuration files.

      "Object" form shall mean any form resulting from mechanical
      transformation or translation of a Source form, including but
      not limited to compiled object code, generated documentation,
      and conversions to other media types.

      "Work" shall mean the work of authorship, whether in Source or
      Object form, made available under the License, as indicated by a
      copyright notice that is included in or attached to the work
      (an example is provided in the Appendix below).

      "Derivative Works" shall mean any work, whether in Source or Object
      form, that is based on (or derived from) the Work and for which the
      editorial revisions, annotations, elaborations, or other modifications
      represent, as a whole, an original work of authorship. For the purposes
      of this License, Derivative Works shall not include works that remain
      separable from, or merely link (or bind by name) to the interfaces of,
      the Work and Derivative Works thereof.

      "Contribution" shall mean any work of authorship, including
      the original version of the Work and any modifications or additions
      to that Work or Derivative Works thereof, that is intentionally
      submitted to Licensor for inclusion in the Work by the copyright owner
      or by an individual or Legal Entity authorized to submit on behalf of
      the copyright owner. For the purposes of this definition, "submitted"
      means any form of electronic, verbal, or written communication sent
      to the Licensor or its representatives, including but not limited to
      communication on electronic mailing lists, source code control systems,
      and issue tracking systems that are managed by, or on behalf of, the
      Licensor for the purpose of discussing and improving the Work, but
      excluding communication that is conspicuously marked or otherwise
      designated in writing by the copyright owner as "Not a Contribution."

      "Contributor" shall mean Licensor and any individual or Legal Entity
      on behalf of whom a Contribution has been received by Licensor and
      subsequently incorporated within the Work.

   2. Grant of Copyright License. Subject to the terms and conditions of
      this License, each Contributor hereby grants to You a perpetual,
      worldwide, non-exclusive, no-charge, royalty-free, irrevocable
      copyright license to reproduce, prepare Derivative Works of,
      publicly display, publicly perform, sublicense, and distribute the
      Work and such Derivative Works in Source or Object form.

   3. Grant of Patent License. Subject to the terms and conditions of
      this License, each Contributor hereby grants to You a perpetual,
      worldwide, non-exclusive, no-charge, royalty-free, irrevocable
      (except as stated in this section) patent license to make, have made,
      use, offer to sell, sell, import, and otherwise transfer the Work,
      where such license applies only to those patent claims licensable
      by such Contributor that are necessarily infringed by their
      Contribution(s) alone or by combination of their Contribution(s)
      with the Work to which such Contribution(s) was submitted. If You
      institute patent litigation against any entity (including a
      cross-claim or counterclaim in a lawsuit) alleging that the Work
      or a Contribution incorporated within the Work constitutes direct
      or contributory patent infringement, then any patent licenses
      granted to You under this License for that Work shall terminate
      as of the date such litigation is filed.

   4. Redistribution. You may reproduce and distribute copies of the
      Work or Derivative Works thereof in any medium, with or without
      modifications, and in Source or Object form, provided that You
      meet the following conditions:

      (a) You must give any other recipients of the Work or
          Derivative Works a copy of this License; and

      (b) You must cause any modified files to carry prominent notices
          stating that You changed the files; and

      (c) You must retain, in the Source form of any Derivative Works
          that You distribute, all copyright, patent, trademark, and
          attribution notices from the Source form of the Work,
          excluding those notices that do not pertain to any part of
          the Derivative Works; and

      (d) If the Work includes a "NOTICE" text file as part of its
          distribution, then any Derivative Works that You distribute must
          include a readable copy of the attribution notices contained
          within such NOTICE file, excluding those notices that do not
          pertain to any part of the Derivative Works, in at least one
          of the following places: within a NOTICE text file distributed
          as part of the Derivative Works; within the Source form or
          documentation, if provided along with the Derivative Works; or,
          within a display generated by the Derivative Works, if and
          wherever such third-party notices normally appear. The contents
          of the NOTICE file are for informational purposes only and
          do not modify the License. You may add Your own attribution
          notices within Derivative Works that You distribute, alongside
          or as an addendum to the NOTICE text from the Work, provided
          that such additional attribution notices cannot be construed
          as modifying the License.

      You may add Your own copyright statement to Your modifications and
      may provide additional or different license terms and conditions
      for use, reproduction, or distribution of Your modifications, or
      for any such Derivative Works as a whole, provided Your use,
      reproduction, and distribution of the Work otherwise complies with
      the conditions stated in this License.

   5. Submission of Contributions. Unless You explicitly state otherwise,
      any Contribution intentionally submitted for inclusion in the Work
      by You to the Licensor shall be under the terms and conditions of
      this License, without any additional terms or conditions.
      Notwithstanding the above, nothing herein shall supersede or modify
      the terms of any separate license agreement you may have executed
      with Licensor regarding such Contributions.

   6. Trademarks. This License does not grant permission to use the trade
      names, trademarks, service marks, or product names of the Licensor,
      except as required for reasonable and customary use in describing the
      origin of the Work and reproducing the content of the NOTICE file.

   7. Disclaimer of Warranty. Unless required by applicable law or
      agreed to in writing, Licensor provides the Work (and each
      Contributor provides its Contributions) on an "AS IS" BASIS,
      WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
      implied, including, without limitation, any warranties or conditions
      of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
      PARTICULAR PURPOSE. You are solely responsible for determining the
      appropriateness of using or redistributing the Work and assume any
      risks associated with Your exercise of permissions under this License.

   8. Limitation of Liability. In no event and under no legal theory,
      whether in tort (including negligence), contract, or otherwise,
      unless required by applicable law (such as deliberate and grossly
      negligent acts) or agreed to in writing, shall any Contributor be
      liable to You for damages, including any direct, indirect, special,
      incidental, or consequential damages of any character arising as a
      result of this License or out of the use or inability to use the
      Work (including but not limited to damages for loss of goodwill,
      work stoppage, computer failure or malfunction, or any and all
      other commercial damages or losses), even if such Contributor
      has been advised of the possibility of such damages.

   9. Accepting Warranty or Additional Liability. While redistributing
      the Work or Derivative Works thereof, You may choose to offer,
      and charge a fee for, acceptance of support, warranty, indemnity,
      or other liability obligations and/or rights consistent with this
      License. However, in accepting such obligations, You may act only
      on Your own behalf and on Your sole responsibility, not on behalf
      of any other Contributor, and only if You agree to indemnify,
      defend, and hold each Contributor harmless for any liability
      incurred by, or claims asserted against, such Contributor by reason
      of your accepting any such warranty or additional liability.

   END OF TERMS AND CONDITIONS

   APPENDIX: How to apply the Apache License to your work.

      To apply the Apache License to your work, attach the following
      boilerplate notice, with the fields enclosed by brackets "{}"
      replaced with your own identifying information. (Don't include
      the brackets!)  The text should be enclosed in the appropriate
      comment syntax for the file format. We also recommend that a
      file or class name and description of purpose be included on the
      same "printed page" as the copyright notice for easier
      identification within third-party archives.

   Copyright 2019 Nils Reimers

   Licensed under the Apache License, Version 2.0 (the "License");
   you may not use this file except in compliance with the License.
   You may obtain a copy of the License at

       http://www.apache.org/licenses/LICENSE-2.0

   Unless required by applicable law or agreed to in writing, software
   distributed under the License is distributed on an "AS IS" BASIS,
   WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
   See the License for the specific language governing permissions and
limitations under the License.
Sentence Transformers 上游通知
以下保留官方源码仓库的 NOTICE.txt,与上文完整 Apache License 2.0 一起适用于所引用的上游代码;不据此扩张第三方模型、数据集或文档的许可范围。
-------------------------------------------------------------------------------
Sentence Transformers

Copyright 2019-2025
Ubiquitous Knowledge Processing (UKP) Lab
Technische Universität Darmstadt

Copyright 2025-present
Hugging Face, Inc.
-------------------------------------------------------------------------------











暂无评论内容